I went into this experiment anticipating a behavioral harness to assist a coding agent meet the necessities extra reliably, save tokens and stop wasted work. Giving an agent clear architectural contracts and deterministic take a look at suggestions whereas it coded appeared like an apparent approach to assist it get the implementation proper on the primary go.
For GPT-6 Sol, the harness used about 10.5 occasions as many tokens, took practically 3 occasions as lengthy, and price about 7 occasions extra, but each situations succeeded in all 10 runs.
The outcomes flatly contradicted that expectation and shocked me. Utilizing Codex with GPT-6 Sol at low reasoning effort, the agent produced an software that handed all 178 automated acceptance exams in every of the ten runs, each with and with out the harness. By this measure, the harness produced no observable enchancment within the ultimate purposes.
GPT-6 Sol (10-run averages for tokens, time, and price):
| Harness | Tokens | Time | Estimated price | Accepted runs |
|---|---|---|---|---|
| Sure | 11,331,970 | 19 minutes 53 secs | ~$2.679 | 10 of 10 |
| No | 1,076,371 | 6 minutes 51 secs | ~$0.406 | 10 of 10 |
The harness elevated common time and price with out altering the noticed acceptance consequence. In exploratory runs with Claude Sonnet 4.6, Claude Opus 4.6, and Gemini 3.8 Flash (all at low reasoning effort), every additionally managed to finish the duty unassisted on the primary strive.
These frontier fashions dealt with this job constantly with and with out the harness. Might executable suggestions assist a cost-optimized mannequin obtain equally constant outcomes?
Earlier than trying on the outcomes for a cost-optimized mannequin, right here is how I arrange the experiment:
Experiment setup
Borrowing Birgitta Böckeler’s framing, a behavioral harness combines guides and sensors. Guides anticipate the place the agent would possibly go unsuitable and steer it earlier than it acts, growing the prospect of an accurate first try. Sensors observe the outcomes after it acts and supply suggestions that helps it self-correct.
For every mannequin, I in contrast brokers working with and with out the behavioral harness. Each situations started with the applying temporary and baseline repository directions in separate, non-public workspaces. Harnessed brokers additionally acquired the API specs, examples, and instruments described within the inner-loop part beneath.
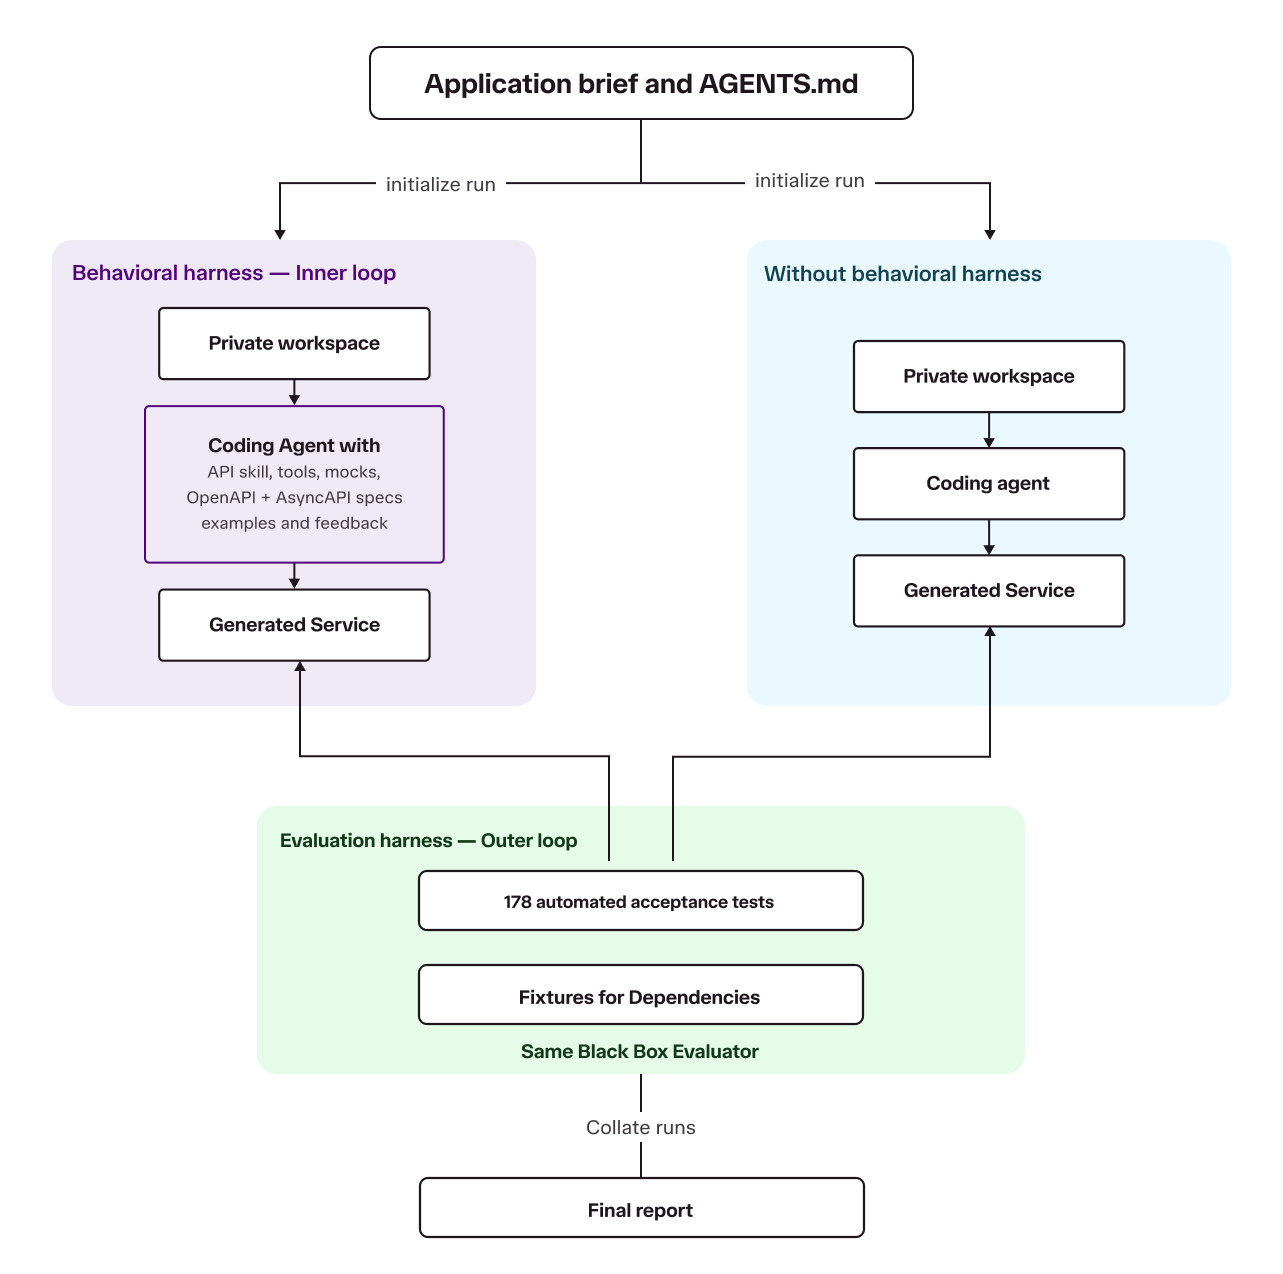
Determine 1: The 2 improvement situations and their unbiased analysis
The experiment separated improvement from analysis into two distinct loops. The inside loop offered suggestions to harnessed brokers whereas they constructed. As soon as an agent completed, the outer loop ran 178 automated acceptance exams towards its generated service. Each situations confronted the identical analysis, and the inside harness by no means had entry to the analysis suite’s reply key. Lastly, I collated the accepted outcomes, token use, time, and estimated price.
On this experiment, I handled an software as acceptable provided that it began efficiently and handed all 178 exterior acceptance exams. Reliability meant how constantly a mannequin produced a suitable software throughout repeated runs. Token use, elapsed time, and estimated price had been separate measures of run effectivity.
The applying temporary
Each try started with an in depth software temporary. I described what the service ought to do, however left the code-level implementation particulars to the agent.
The duty was to construct a backend-for-frontend (BFF) for product discovery. It needed to expose a consumer-facing HTTP API, validate incoming requests and downstream responses, and name an Order API. After a profitable availability search, it additionally needed to publish solely the primary returned product to Kafka. Publishing each product would have allowed the agent to go the information by means of with out implementing the choice habits.
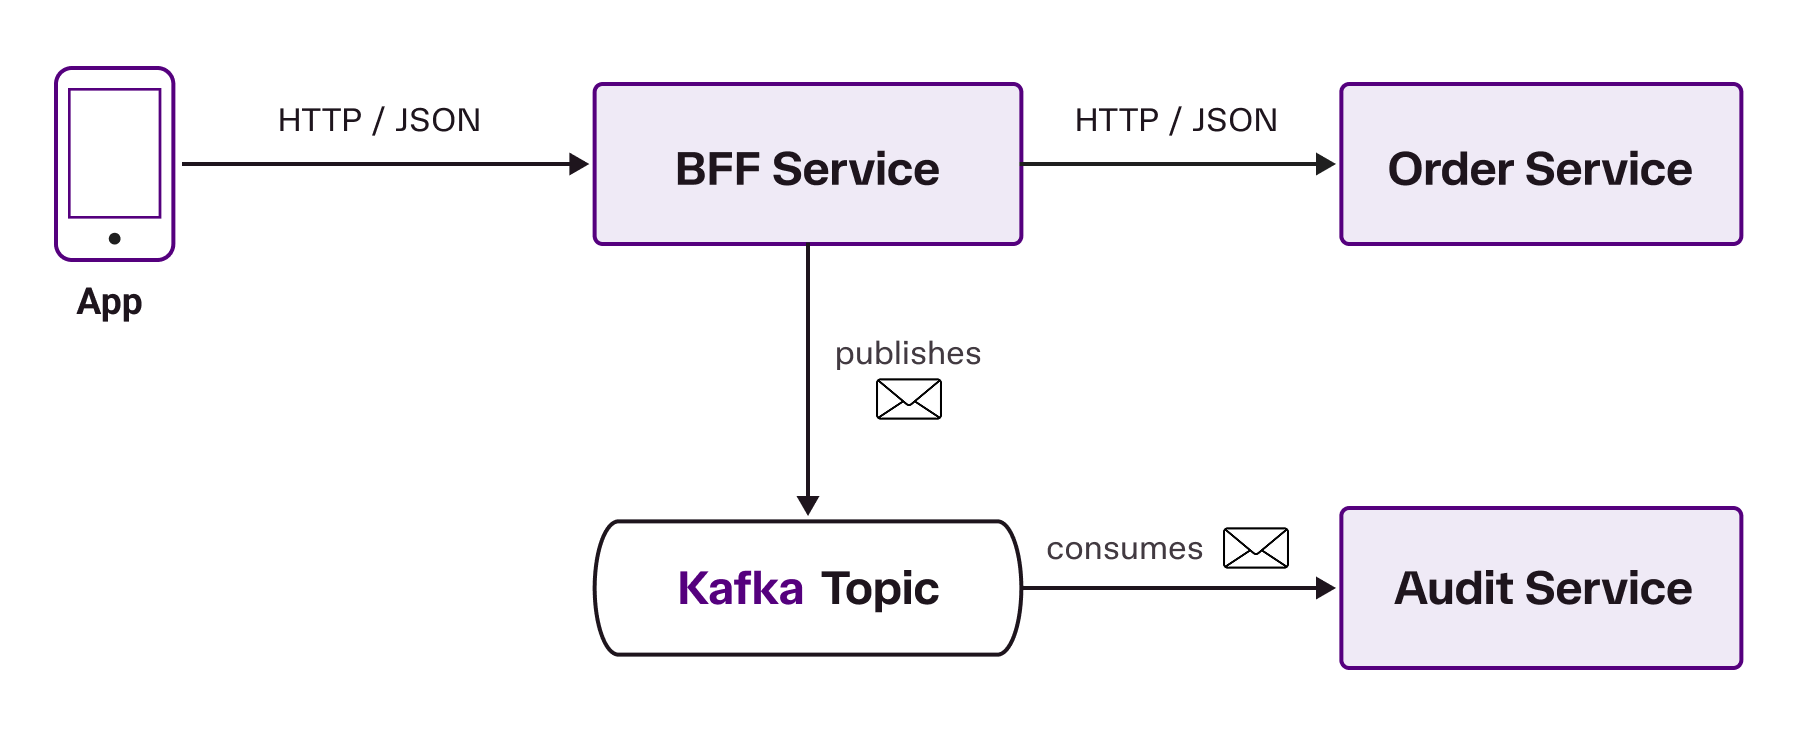
Determine 2: The applying structure described by the temporary
The temporary additionally specified much less apparent habits. A timed-out product creation needed to develop into a deferred request with a 202 response code and a hyperlink within the response header that customers might ballot for a response. A transient search failure needed to return 429 with a usable restoration interval; unavailable dependencies or failed occasion publication needed to develop into 503; and profitable downstream responses nonetheless needed to obey requested product filters or in any other case return 502.
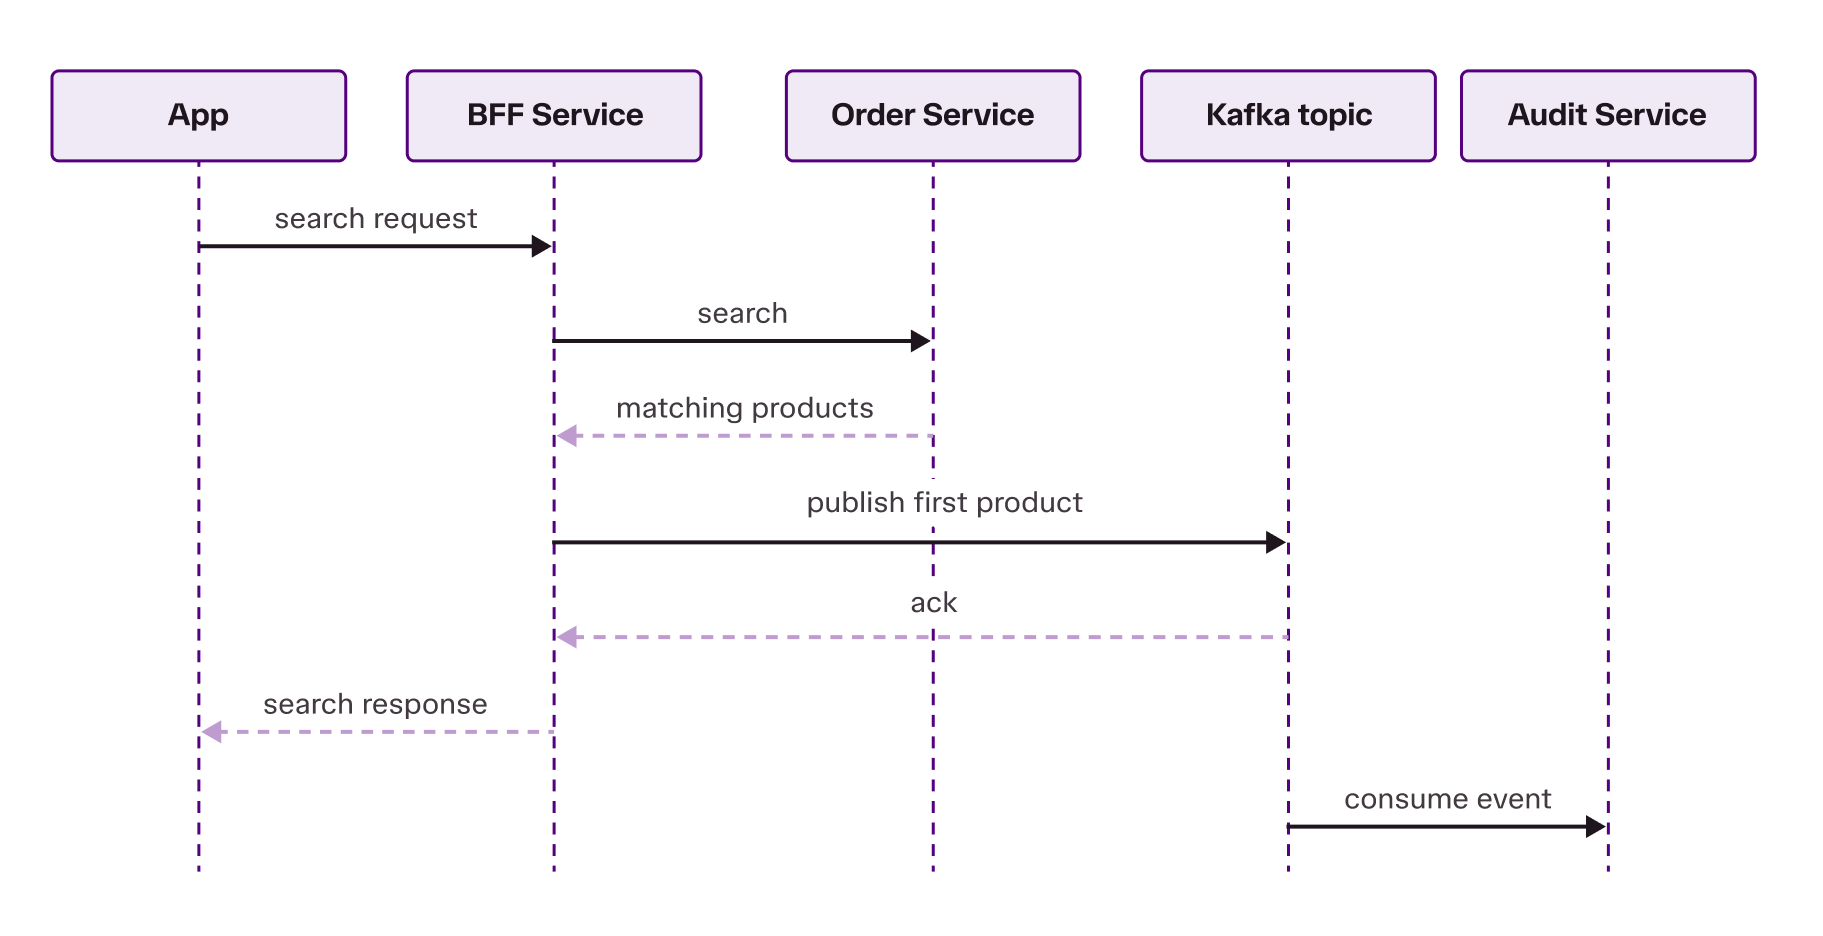
Determine 3: A profitable availability search and its Kafka publication
Briefly, the service was greater than a set of CRUD endpoints: the agent needed to coordinate HTTP semantics, asynchronous occasions, schema boundaries, and fault-tolerance insurance policies concurrently.
This was additionally a positive start line for an unaided agent: the temporary spelled out the practical necessities, architectural and expertise constraints, detailed descriptions of the exterior interfaces, response shapes, and failure habits in uncommon element. I don’t but understand how the outcomes would change with a much less full temporary.
The inside loop: behavioral harness
On this experiment, the guides included OpenAPI and AsyncAPI specs that expressed the interface agreements in machine-readable kind, offering a foundation for executable checks. They complemented the temporary slightly than defining a separate set of necessities. The guides additionally contained request-response examples for these interfaces. The examples lined downstream timeouts, malformed payloads, filter violations, retry sequences, and Kafka occasion confirmations. An API-development talent equipped implementation practices and steerage on dependency simulation, behavioral verification, and learn how to diagnose and reply to failures.
The sensors checked contract conformance, used API exams to confirm HTTP response values, and asserted observable unwanted effects, together with calls to downstream mocks and Kafka publication. Check outcomes, CTRF reviews, and API protection reviews returned these observations to the agent throughout improvement.
Birgitta additionally distinguishes computational controls, executed by deterministic instruments, from inferential controls, which depend on mannequin interpretation or judgment. This harness mixed each. The behavioral checks produced computational suggestions with out an LLM judging correctness. Guided by the talent’s directions, the agent nonetheless needed to interpret these outcomes and resolve learn how to repair failures.
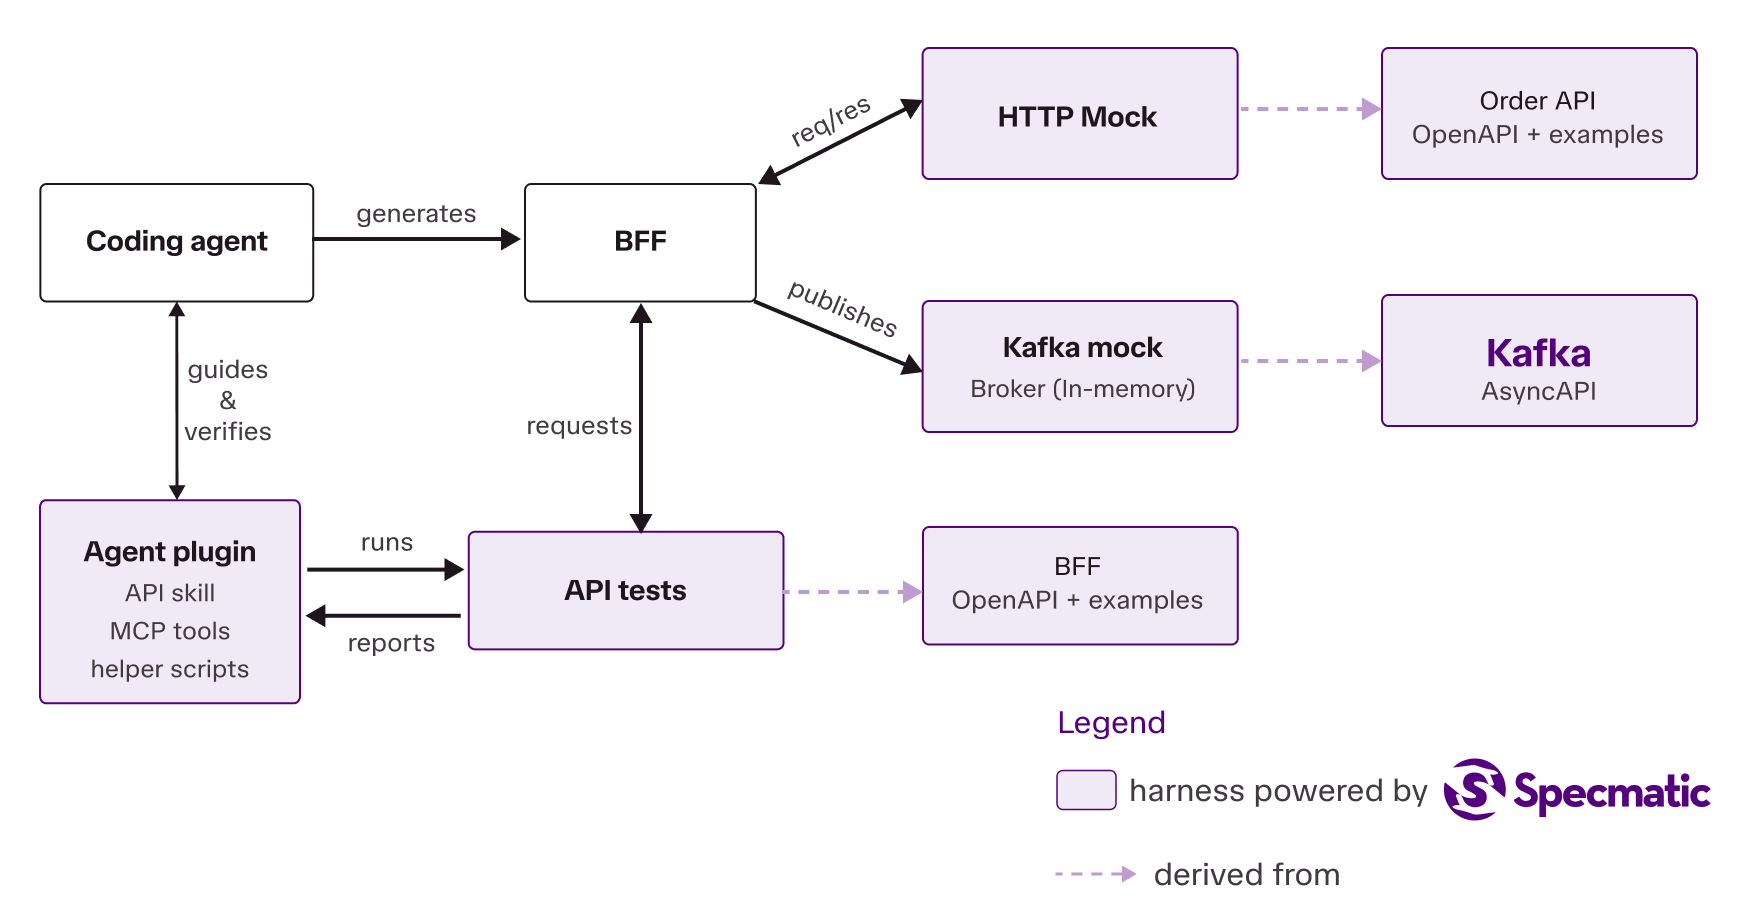
Determine 4: The behavioral harness and its suggestions paths
An agent plugin equipped the talent and MCP instruments, accompanied by the contracts and examples. The OpenAPI specs lined the BFF and downstream Order API; the AsyncAPI specification lined Kafka.
Earlier than implementing the service, the agent learn the specs and examples alongside the temporary. The talent directed it to map the applying’s elements and hyperlink every required habits to its downstream interactions and verification checks. Helper scripts scaffolded these paperwork, a report of verification proof, and the instructions for constructing, beginning, and testing the service; the agent accomplished the behavior-specific particulars.
Configuration instruments wired the contracts to the applying and dependency mocks. Contract-driven dependency mocks made downstream interactions executable, permitting the agent to train its implementation towards outlined downstream responses, failures, and restoration sequences. Different helpers verified timing constraints. Collectively, these instruments offered each implementation steerage and an executable setting through which the agent might test its selections.
The agent invoked the harness by means of the challenge’s take a look at command. That command validated the configuration and examples, ran the required construct and unit checks, began the downstream mocks, and launched the applying towards them. It then ran the checks described above.
Report summaries recognized particular contract, response worth, and interplay mismatches. The agent used the talent’s directions to diagnose them, change the implementation or execution setup, and use a helper to rerun the affected eventualities. As soon as these eventualities handed, the agent ran the whole suite as a ultimate gate. The suggestions loop trusted the agent invoking these instruments throughout improvement; it didn’t run routinely after each code edit.
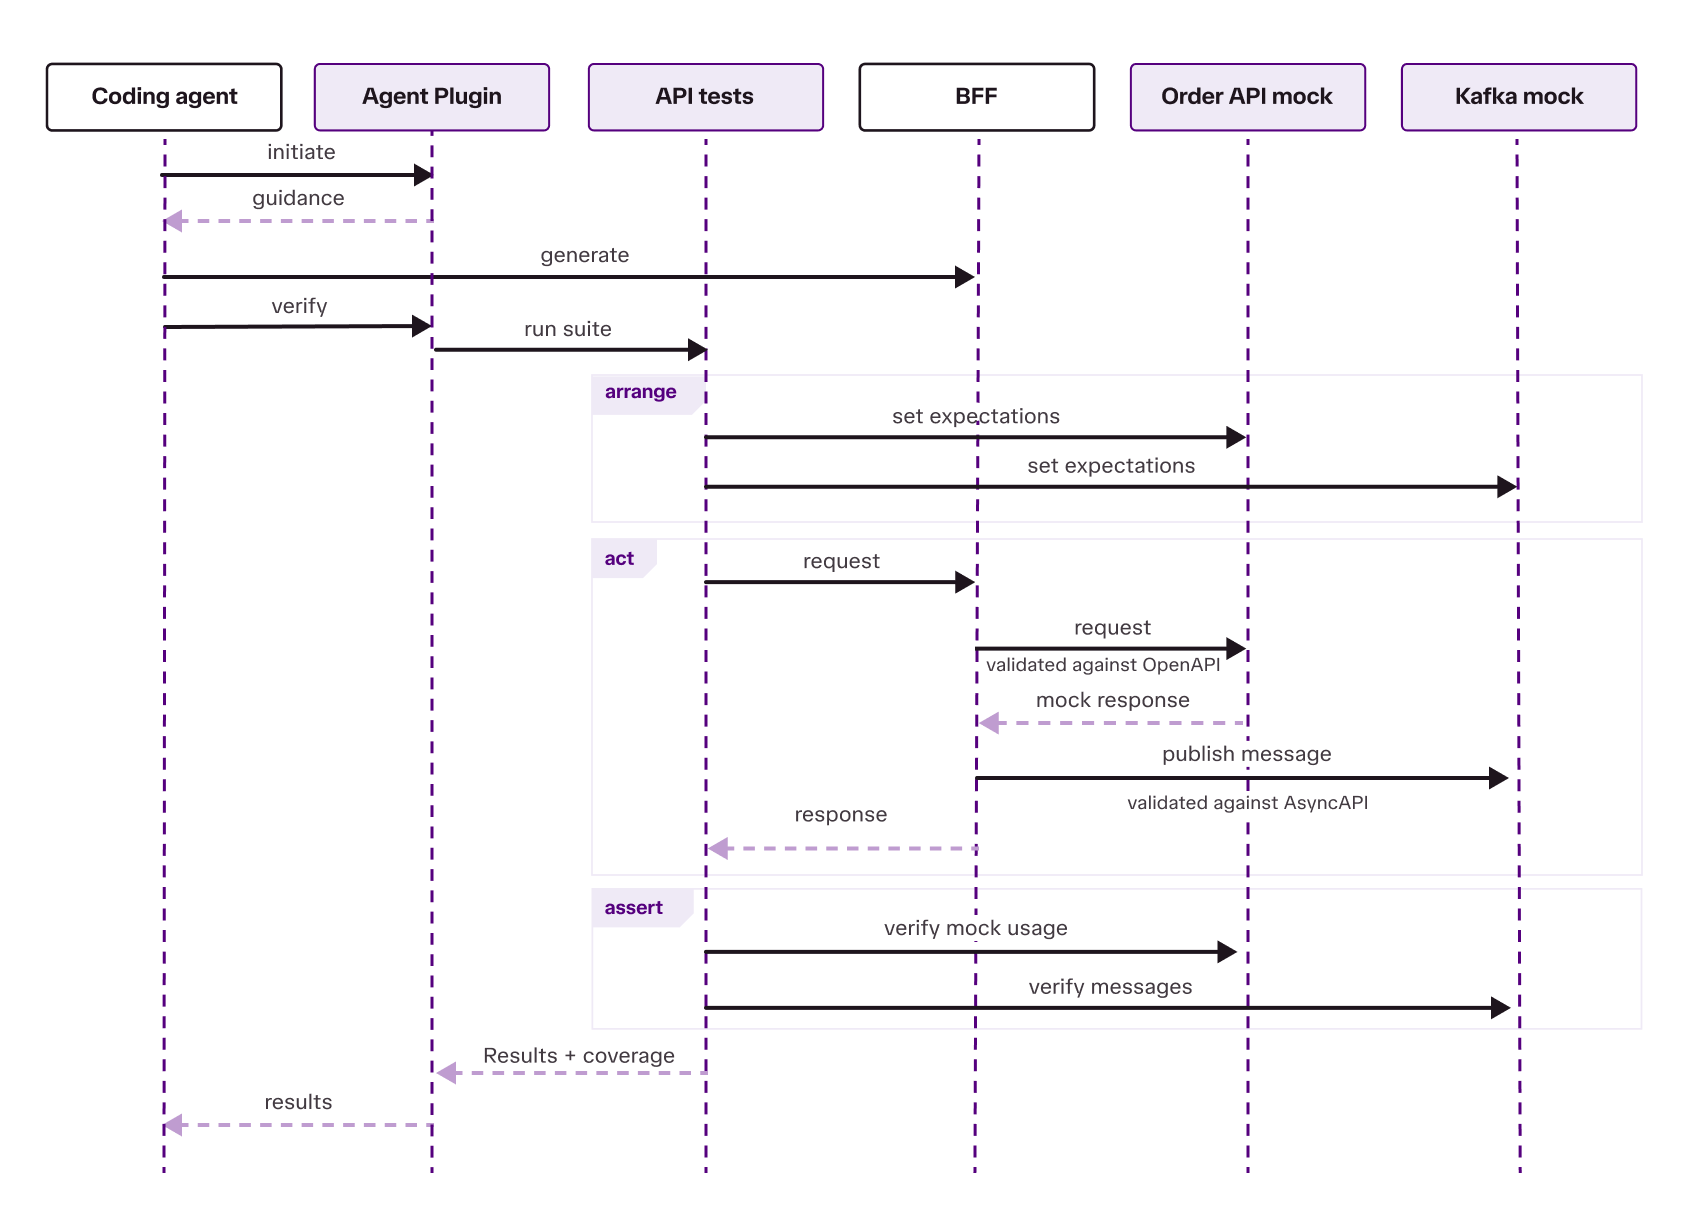
Determine 5: The inner-loop take a look at and suggestions sequence
Conserving guides and sensors in sync
One of many large challenges of designing such a behavioral harness is to ensure the guides and sensors do not contradict one another and confuse the brokers. I addressed this difficulty with the next strategy:
Earlier than working any exams, an “examples validate” command checked that the instance payloads complied with the respective API specs. Exams then used these specs and examples to test the implementation, retaining the sensors aligned with their supply guides.
The supply of these checks mattered. If an agent interprets necessities to put in writing each the implementation and its exams, the identical misreading or omission can seem in each. Permitting it to vary the anticipated outcomes when exams fail can even obscure a defect. Right here, the contracts and examples characterize agreed human expectations in executable kind. Contract checks had been generated deterministically from equipped specs, whereas equipped examples with behavioral fixtures outlined worth and side-effect assertions. The agent was instructed to protect these inputs and the talent’s verification helpers, examine failures, and proper the implementation or execution setup slightly than weaken the expectations.
This gave verification expectations a supply unbiased of the implementing agent’s interpretation. Used as a deterministic computational management, they make correctness checkable with out counting on the agent’s personal claims or an LLM’s judgment, releasing people to focus assessment on what the contracts do not cowl.
The identical sensors subsequently serve two distinct functions relying on once they run:
- Throughout improvement: Sensor outcomes feed again to the agent as executable consideration, steering building and serving to it recuperate from lapses.
- At completion: Sensor outcomes develop into the premise for accepting the work: an unbiased test of the agent’s interpretation towards human expectations, which issues for each mannequin.
The talent additionally required reviewable proof of dependency interactions and the ultimate verification consequence, so completion was supported by recorded observations slightly than the agent’s declare alone.
On this experiment, I carried out the behavioral harness utilizing Specmatic, although equal contract-testing and repair virtualization instruments might present the identical capabilities.
The outer loop: analysis harness
To maintain the comparability honest, every try ran inside an remoted Docker container with its personal workspace and a contemporary, attempt-specific Codex house. Aside from shared authentication and language dependency caches, every agent started with out classes, recollections, plugins, abilities, or different state from an earlier run.
The 2 situations differed in what brokers might use throughout improvement; inside every comparability, accomplished purposes confronted the identical exterior analysis.
After improvement stopped, the outer-loop analysis harness examined every software towards the identical corpus of 178 mixed practical checks, together with invalid inputs, downstream failures, restoration sequences, and the messages produced by profitable requests. These checks exercised the habits specified within the software temporary, together with the client-facing API, downstream interactions, and Kafka publication. The analysis harness managed its personal downstream fixtures and message seize slightly than counting on the applying’s improvement exams.
Testing a cost-optimized mannequin
OpenAI positions GPT-6 Sol as a flagship mannequin for advanced skilled work, whereas GPT-6 Luna is optimized for cost-sensitive, high-volume workloads and roughly corresponds to the nano tier in earlier GPT-5 households.
With the methodology in place, the core query is whether or not a mannequin with a smaller functionality profile would behave otherwise.
I ran the very same experiment on GPT-6 Luna at low reasoning effort. With out a harness, it succeeded in 3 of 10 runs. With the harness, it succeeded in all 10.
GPT-6 Luna (10-run averages for tokens, time, and price):
| Harness | Tokens | Time | Estimated price | Accepted runs |
|---|---|---|---|---|
| Sure | 22,933,648 | 35 minutes | ~$0.273 | 10 of 10 |
| No | 5,860,736 | 15 minutes 56 secs | ~$0.086 | 3 of 10 |
On this pattern, the harness didn’t unlock a functionality Luna lacked; it turned a 3-in-10 baseline into 10-for-10 reliability.
Offering that suggestions added a median of 17,072,912 tokens, 19 minutes 4 seconds of autonomous runtime, and about $0.187 of estimated API-equivalent price per try. The harnessed try used roughly 3.9 occasions as many tokens general as an unharnessed Luna try. However have a look at the comparative economics: even with the harness overhead, a harnessed Luna try price about 33% lower than an unharnessed Sol try ($0.273 vs $0.406), and each situations achieved the identical 10-for-10 acceptance charge on this pattern.
What went higher than anticipated
Trying previous the headline go charges into the codebase, a number of implementations stood out:
- GPT-6 Sol solved the temporary unaided in a single shot.
A single
/purposeimmediate was sufficient. All 10 unharnessed GPT-6 Sol purposes handed each practical test on the primary go with out human debugging or corrective follow-ups. - GPT-6 Luna got here remarkably shut by itself.
Unharnessed GPT-6 Luna runs handed 94.8% of the practical checks. It was stumbling over delicate edge instances slightly than lacking the duty solely.
- Asynchronous 202 workflows held collectively end-to-end.
Returning a
202 Acceptedstanding code is easy. What shocked me was seeing the agent wire up the monitor endpoint, monitor pending requests, retry downstream creation with the unique idempotency key, and floor the ultimate payload on the polling URL. - Kafka publication stayed tied to the search transaction.
Moderately than firing off a message asynchronously and returning an instantaneous
200, accepted purposes waited for Kafka acknowledgement earlier than responding, and appropriately translated publication failures or timeouts into503 Service Unavailable. - Boundary validation was constantly defensive.
Each fashions validated incoming payloads towards schemas and validated downstream response constructions and enterprise constraints earlier than utilizing the information, slightly than blindly trusting downstream providers.
The place unharnessed runs slipped up
The failed unharnessed Java purposes didn’t comprise invalid syntax or essentially misunderstand the temporary. Every nonetheless handed a minimum of 144 of the 178 mixed practical checks. Their failures clustered across the deferred creation workflow and a smaller set of protocol particulars:
The noticed gaps appeared at protocol boundaries, resiliency paths, and integration seams, the place a convincing implementation might nonetheless fail as a system.
- Deferred creation broke on the timeout boundary.
When a downstream product creation exceeded the configured timeout, the BFF was speculated to return
202 Acceptedwith a monitor hyperlink, retry within the background, and finally expose the downstream201response. As an alternative, 4 unharnessed purposes returned503, 2 returned400, and 1 returned429. An software already counted above additionally created displays in some eventualities, however its retries by no means reached the terminal201response. A number of implementations acknowledged timeouts by matching a slender exception kind or cause-chain form. The artifacts set up the inaccurate responses, however typically don’t report the precise consumer exception, in order that mechanism is a probable rationalization slightly than a confirmed frequent trigger. - Lacking monitor hyperlinks brought on secondary failures.
In 7 runs, the inaccurate response to the timed-out creation additionally meant that no monitor URL was returned. A later evaluator test then failed whereas making an attempt to make use of that lacking URL. I deal with these errors as penalties of the damaged
202circulation, not as separate software defects. - Kafka supply succeeded whereas contract conformance failed.
In 3 runs, each anticipated message reached Kafka, however the evaluator nonetheless rejected the publication. Two purposes used Spring’s JSON serializer and added an surprising
__TypeId__header. One other emitted“classes”: null, although the non-compulsory subject needed to comprise an array when current. The combination labored mechanically whereas nonetheless violating the wire contract. - Error responses missed actual HTTP contracts.
Different noticed misses had been narrower. Though
415 Unsupported Media Sortis a standard response for an unsupported media kind, the applying temporary explicitly required400for invalid requests of this sort, so the evaluator counted415as a contract violation. In different instances, invalid requests reached a generic500handler, and a lacking monitor returned the unsuitable illustration. These had been small variations in code, however sufficient to make the applying unacceptable underneath the exterior analysis. - Configuration names diverged at an integration seam.
Abnormal product creation returned
503as an alternative of201. The generated consumer learnORDER_API_API_KEY, whereas the recorded launch equippedORDER_API_KEY. That mismatch is a believable rationalization for the downstream failures. In harnessed runs, contract-driven dependency mocks and configuration checks enabled validations of those setting variables earlier than deployment.
The harness as executable consideration
A behavioral harness turns written necessities into environmental suggestions, bringing dropped particulars again into focus when a sensor goes crimson.
I discover myself occupied with this dynamic when it comes to executable consideration.
The behaviors behind these failures had been specified within the equipped necessities. The applying temporary clearly specified the deferred creation workflow, Kafka message contract, and actual error responses. A requirement may be express within the temporary and nonetheless lose affect throughout implementation. I consider this as an consideration lapse: the ensuing code omits or incompletely implements a requirement the agent was given.
Juggling library selections, boilerplate setup, dependency injection, and asynchronous wiring throughout a rising context might contribute to such lapses, though this experiment didn’t set up the trigger. Executable consideration makes these gaps observable, giving the agent one other alternative to behave on the requirement.
- A timed-out creation is not deferred till the response features a monitor hyperlink and polling finally reaches the downstream consequence.
- A Kafka publication is not legitimate merely as a result of a message arrived; its payload and headers should each conform to the wire contract.
- An non-compulsory subject can’t be serialized as
nullwhen the contract permits solely an array or omission. - An error response is not right except its standing, content material kind, and physique all match the client-facing contract.
GPT-6 Sol preserved these particulars from the written temporary in all noticed runs. GPT-6 Luna additionally carried out a lot of the habits appropriately with out the harness, however its accepted outcomes different. The misses in Luna are per necessities dropping affect throughout implementation. My interpretation is that the harness served as an exterior reminiscence and a focus help, pulling dropped necessities again into focus each time a sensor went crimson.
The economics of constant outcomes
Placing each mannequin samples aspect by aspect makes the price of that suggestions seen. These are API-equivalent estimates based mostly on recorded token use and mannequin costs, not precise billed prices.
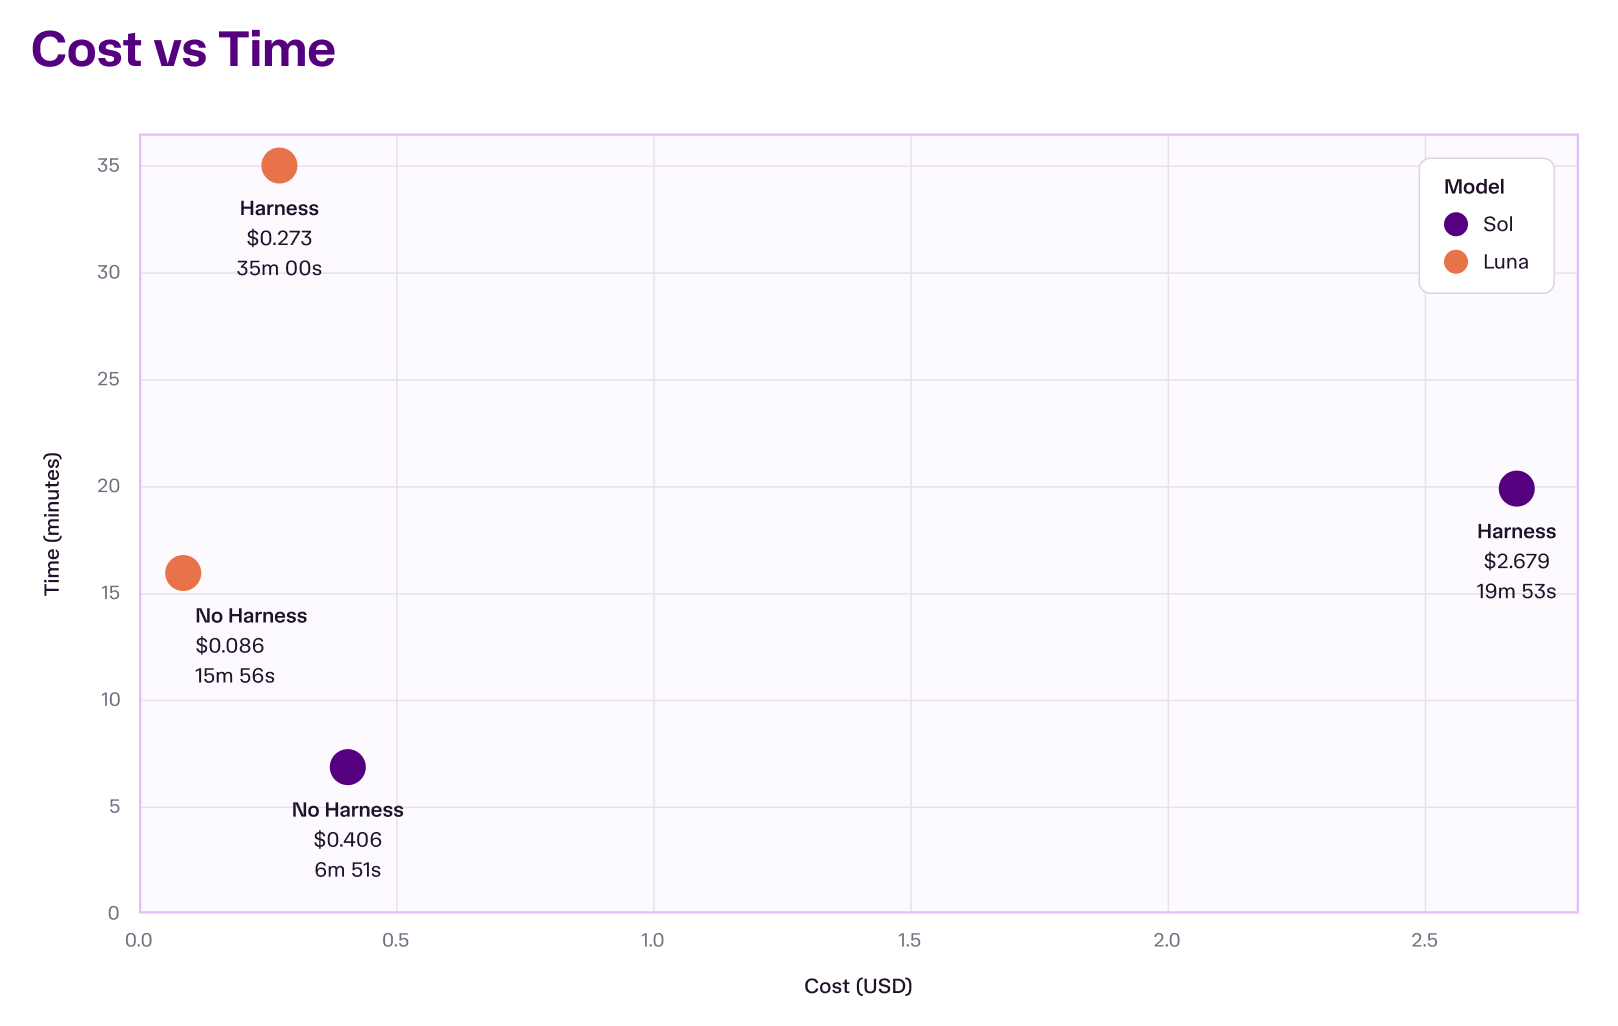
Determine 6: Common estimated price and time throughout each fashions
Inside the GPT-6 runs, harnessed Luna averaged about $0.273 per try, in contrast with $0.406 for unharnessed Sol; each had 10 accepted purposes in 10 makes an attempt. The harnessed Luna try subsequently price about 33% much less on common on this pattern.
All 10 harnessed GPT-6 Luna purposes handed the exterior analysis and achieved a 100% success charge. This small pattern can not inform us the long-run failure charge or the entire price of reaching a suitable software.
These figures measure solely autonomous era price and machine time. They exclude the upfront effort of authoring, reviewing, and sustaining the contracts, examples, assertions, and harness. Additionally they omit the hassle of discovering, diagnosing, and repairing an unacceptable consequence. Reusing interface contracts and checks throughout implementations might unfold the setup price over time, however I didn’t measure that reuse or the ensuing complete price.
Sol’s 10-for-10 consequence nonetheless trusted unbiased analysis. That implies one other comparability: make the sensors out there to the agent solely at a ultimate verification gate, slightly than all through improvement. A final-gate workflow would supply an unbiased acceptance test whereas minimizing overhead when the primary implementation passes. Failures, nonetheless, might nonetheless require prognosis and restore cycles. I didn’t measure that workflow’s price.
The boundaries of this experiment
This experiment lined 10 paired runs per mannequin on 1 greenfield Java service, with each fashions at low reasoning effort. That pattern describes the noticed outcomes; it can not set up long-run reliability.
A extra demanding structure or a trickier resiliency situation would possibly expose gaps in Sol that require a harness. Conversely, a less complicated job would possibly run reliably on Luna with out this behavioral harness.
The temporary specified practical habits, structure, expertise, and interfaces in uncommon element. I’ve not examined whether or not the sample holds when modifying legacy code, utilizing different languages or reasoning settings, or working from obscure or incomplete necessities. A much less full temporary might have an effect on each the unaided implementation and the standard of the contracts and examples equipped to the harness. I’d be cautious about extrapolating these actual figures to completely different briefs, architectures, codebases, or group workflows.
As a result of the harness added guides and sensors collectively, this experiment additionally can not isolate their particular person contributions.
What this implies in apply
I’d deal with these outcomes as a place to begin for selecting a mannequin and suggestions cadence for a specific job. What modifications with mannequin functionality is when and the way typically the sensors run, not whether or not an unbiased test is required.
Mannequin functionality modifications when and the way typically sensors run, not whether or not an unbiased verification gate is required.
- For cost-optimized fashions: When a cost-optimized mannequin produces inconsistent outcomes, run a behavioral harness all through improvement. It serves as executable consideration, catching drift because it occurs and turning inconsistent makes an attempt into reliable supply.
- For frontier fashions: Retain an unbiased acceptance test even when a mannequin passes constantly on the primary try. As an alternative of working steady checks throughout improvement, run the automated exams as soon as as a deterministic ultimate verification gate earlier than acceptance, offering an unbiased test with minimal overhead.
- Put money into clear specs and examples: The checks can implement solely the expectations people encode. Evaluate and preserve these expectations alongside the implementation, and use human assessment to deal with gaps in protection.
Conclusion
My unique assumption was too blunt. A behavioral harness will not be an computerized win for each mannequin on each job. For Sol, working the harness all through improvement added overhead with out a detected acceptance profit; for Luna, harnessed makes an attempt had been accepted extra constantly and price much less on common than unharnessed Sol makes an attempt on this pattern.
That leaves me with a revised, conditional speculation:
What modifications with mannequin functionality will not be whether or not unbiased sensors are wanted, however once they run. For fashions whose unaided makes an attempt produce inconsistent outcomes, working sensors constantly throughout improvement supplies executable consideration that broadens the set of fashions a group can use efficiently. For frontier fashions able to fixing the temporary in a single go, working those self same sensors as soon as as an unbiased ultimate acceptance gate supplies the verification each system requires with out the event overhead.
In apply, engineering groups not often decide a mannequin on uncooked benchmark intelligence alone. Unit economics, latency budgets, information privateness, and the flexibility to run on premises typically dominate the choice. If a behavioral harness can take a less expensive, lighter mannequin that already matches these operational constraints and make it reliably ship the products, that could be a compelling possibility.
I’ve examined this thus far on a single greenfield service with an unusually detailed temporary. The subsequent step is to check a “ultimate gate solely” situation for frontier fashions to measure its overhead and the way typically the gate catches discrepancies. Past that, I plan to range the standard of the temporary and the results of a missed requirement, then take a look at how properly this speculation holds up when modifying an current codebase, switching programming languages, or working open-weights fashions domestically.