Search and textual content interfaces have conditioned customers to anticipate helpful outcomes earlier than they’ve completed expressing what they need. A couple of characters typed right into a search bar can produce a ranked set of queries, whereas predictive textual content makes use of {a partially} entered phrase to recommend its completion. Related types of prefix matching function much less visibly in spell checkers, dictionaries, routing tables, and different techniques that should slim a big assortment of attainable outcomes with every new unit of enter.
Nevertheless acquainted the expertise has turn into, delivering it at velocity is tough when the system holds thousands and thousands of saved phrases or queries. If it compares every new prefix in opposition to each saved entry, it should repeat the identical giant scan after each keystroke and floor solutions instantly.
Standard lookup buildings work greatest when the entire search key’s already identified. Prefix-based techniques have much less info to work with as a result of the search begins earlier than the complete key’s identified, which adjustments how the information must be organized, since phrases or queries with the identical sequence must be searchable collectively.
The trie information construction, often known as a prefix tree or digital tree, organizes keys in line with the prefixes they share. Every character types a part of a path by way of the trie, so phrases with the identical starting comply with the identical branches till they diverge. As soon as a system has traversed the nodes related to a prefix, it may well discover attainable completions among the many descendants of that time. The search is, subsequently, dictated by the size of the enter, not by the variety of entries saved.
Drawing on almost three a long time as a Java developer, together with at corporations like Yahoo and Amazon, I discover what makes trie-based prefix search environment friendly, even on a big scale, and which retrieval issues profit most from that design. I additionally study how shared-prefix group influences efficiency and reminiscence use, giving different builders a clearer foundation for deciding when a trie is the proper construction.
Understanding the Trie Knowledge Construction
A trie derives its effectivity from the best way it represents the relationships between keys. The place many information buildings retailer every phrase as a whole worth, a trie divides it right into a sequence of characters related by way of nodes. Keys with the identical opening characters use the identical nodes, making a shared route by way of the trie earlier than branching on the level the place the phrases differ. Understanding this construction explains how a trie can distinguish a whole phrase from a prefix and restrict every search to a related path by way of the saved information.
How a Trie Organizes Knowledge
A trie begins with an empty beginning node, known as the foundation, which connects to nodes representing the primary characters of the saved keys. Every subsequent stage represents the following character within the sequence. In a trie containing “wait” and “water,” for instance, each comply with the identical path by way of the nodes for “w” and “a.” The paths then separate as a result of the third character in every phrase is totally different. The trie shops their frequent starting as soon as and creates separate branches solely the place the phrases diverge.
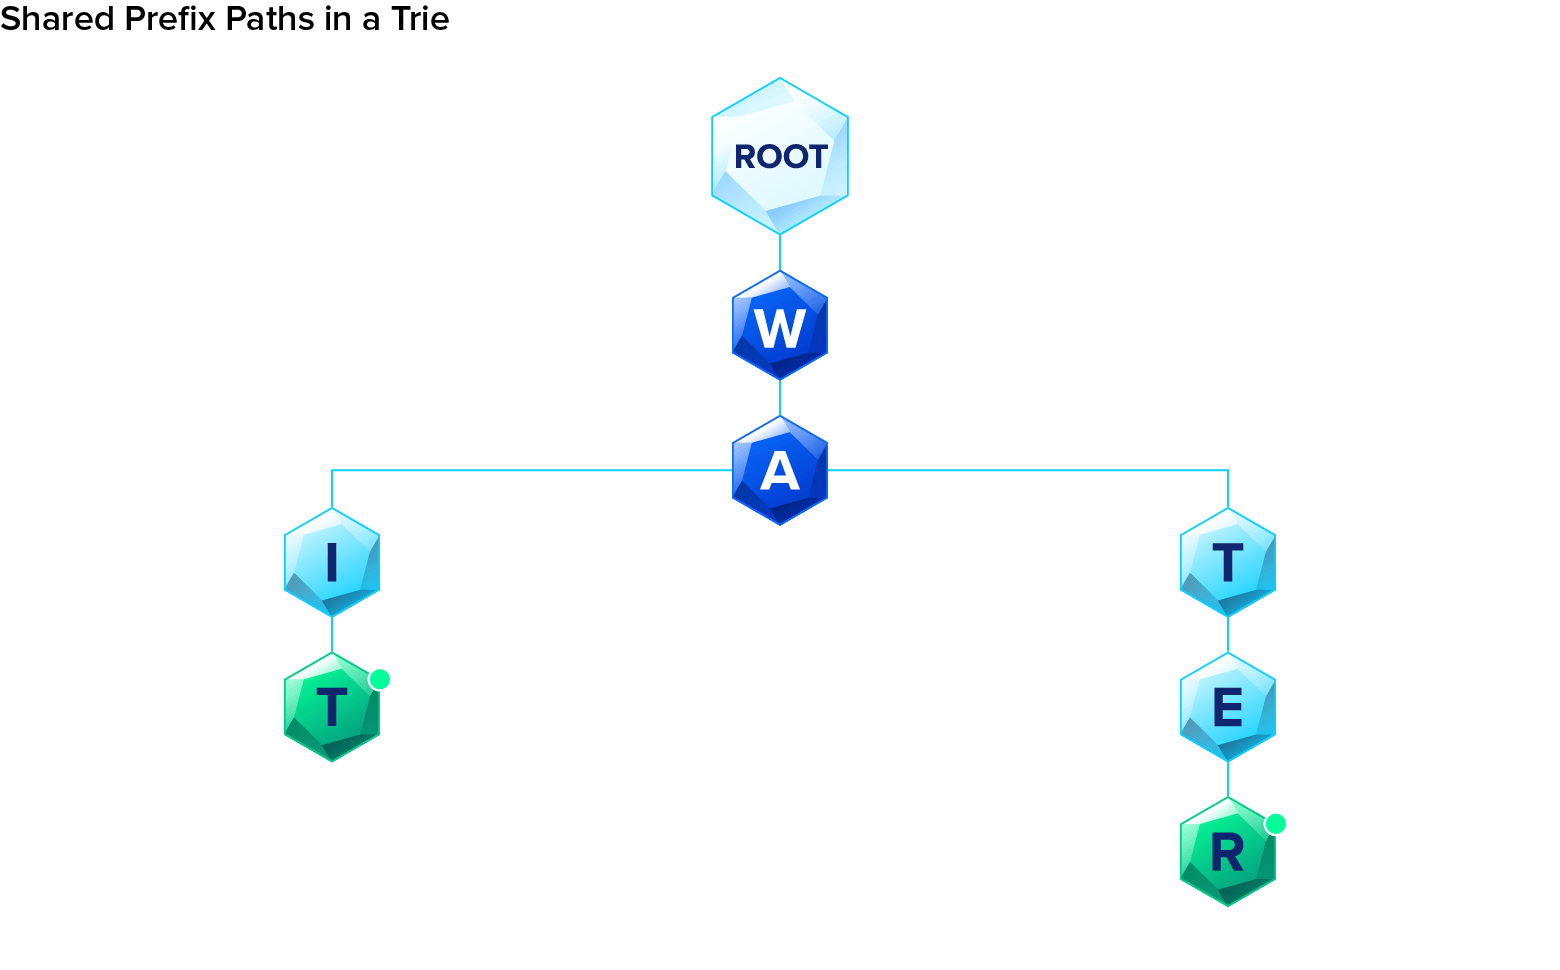
The illustration above exhibits a path for “wa,” however “wa” isn’t saved as a whole phrase. To make that distinction, the trie provides a terminal marker wherever a saved phrase ends. In code, every node sometimes features a Boolean area corresponding to isEndOfWord. The sphere is about to true on the ultimate “t” in “wait” and the “r” in “water,” whereas it stays false on the “a” node as a result of “wa” is simply a prefix.
Core Traits of Tries
The character-by-character group of a trie provides it a unique efficiency profile from buildings the place every key’s a single worth. Discovering a phrase or prefix requires the trie to comply with one node for every character within the enter. The variety of saved keys doesn’t instantly lengthen that path, so a profitable seek for a five-character phrase includes the identical variety of traversal steps whether or not the trie accommodates a couple of hundred entries or a number of million.
With every character, the search strikes additional down one department and leaves extra unrelated keys behind, permitting a prefix question to bypass each department that may’t comprise a match. That progressive narrowing provides tries a number of defining traits:
- Shared prefixes reuse the identical path. In a dataset containing many phrases with a standard starting, the phrases comply with the identical nodes till their characters diverge, limiting the variety of separate paths the trie should create.
- A whole key also can function a prefix. A terminal marker can determine “app” as a saved phrase whereas the identical path continues by way of further nodes for “apple.”
- Ordered traversal can return keys lexicographically. Visiting youngster nodes in character order produces ends in lexicographic order with out requiring a separate sorting step.
Case Examine: Utilizing Shared Prefixes in an EV Charging System
I used this type of prefix-based group whereas engaged on software program for EV charging stations. The system related software program operating on every charger to a cloud platform by way of an middleman machine, which wanted to retailer requests persistently in order that processing might resume from the identical level after an sudden interruption.
Each request ID started with the identifier of the machine from which it originated. We organized these IDs in a trie in line with their shared prefixes, permitting the system to retrieve the requests related to a specific machine utilizing solely its ID. The traversal might comply with that prefix on to the related group with out looking by way of requests generated by each different machine. Every request ID ended with a sequence quantity that positioned it in arrival order when the machine’s department was traversed. After a restart, the middleman might subsequently resume with the following unprocessed request with out reconstructing that order.
The requests had been held in a small doc database as a result of the middleman machine didn’t require the capability of a giant relational system. We separated the persistence layer from the enterprise logic in order that we might check 4 or 5 database applied sciences with out rewriting the remainder of the applying. The choice we chosen required little storage and returned reads inside milliseconds beneath our check situations. As a result of requests from the identical charger shared its machine ID as a prefix, the trie represented that portion of the identifier as soon as and prolonged the trail just for every particular person request. After efficiently processing a request, we deleted it from the trie and pruned any nodes that weren’t wanted to achieve one other saved request. This prevented accomplished work from accumulating on the resource-constrained middleman machine.
Key Trie Operations and Traversal Logic
Trie operations all construct on the identical character-by-character traversal, with every enter character directing the search to the following node. What adjustments is how the trie interprets or modifies that path, relying on the consequence the operation wants to supply.
Search Operations
When a system wants to substantiate {that a} full key’s already saved, it performs a search operation. A spell checker, for instance, may search a dictionary trie to find out whether or not an entered phrase is legitimate.
To verify the candidate phrase in opposition to the saved keys, the trie follows this sequence:
- Start on the root: The search makes use of the primary character within the enter to pick the corresponding youngster node.
- Observe the character path: Every subsequent character determines which youngster node the traversal visits subsequent.
- Cease when a required node is lacking: A damaged path confirms that the secret’s not saved, so the remaining characters don’t must be processed.
- Test the terminal marker: If a full path exists, the search returns true solely when the ultimate node is marked as a whole key. A trie containing “water,” for instance, has a sound path for “wat” however a precise seek for “wat” returns false until that prefix was additionally saved as a phrase.
Insert Operations
An insert operation happens when a brand new key must be added to the saved dataset, like updating a dictionary. As a result of a number of the opening characters are doubtless already saved as a part of one other key, the operation should protect the present path whereas including no matter the brand new entry requires.
The method follows this sequence:
- Start on the root: The primary character determines which youngster path the insertion ought to comply with.
- Reuse the shared prefix: The insertion follows current nodes for so long as they match the incoming characters, permitting keys with the identical starting to make use of a standard path.
- Create the lacking nodes: When no youngster corresponds to the following character, the trie provides one and continues extending the trail till each character has been represented.
- Full the brand new entry: The final node receives a terminal marker so the trie acknowledges the trail as a saved key.
Delete Operations
A delete operation removes a key when the underlying dataset now not contains it. If a retailer discontinues a product, for instance, its title could must be faraway from the autocomplete trie so it now not seems in search solutions. As a result of a number of keys depend on the identical nodes, the operation should take away the goal with out breaking the paths utilized by the remaining entries.
To do that safely, the trie follows this sequence:
- Find the entire key: The trie follows the character path and checks the terminal marker on the remaining node. If the trail is incomplete or the marker is absent, the important thing isn’t saved and nothing is deleted.
- Clear the terminal marker: Eradicating the marker means the trail now not represents the deleted key, though its nodes initially stay in place.
- Take away unused nodes: Ranging from the tip of the important thing, the trie works backward and removes nodes that don’t have any kids and don’t mark one other full key.
- Protect shared paths: Cleanup stops when the trie reaches a node that also has kids or represents one other saved key. This prevents deletion from affecting phrases that share a part of the identical path.
Prefix Matching and Traversal Methods
Prefix matching is used when a system receives a part of a key and desires to seek out the saved entries that start with it. An autocomplete system, for instance, may obtain “wat” and return “water.”
To find attainable matches, the trie follows the characters within the prefix till it reaches the corresponding node. If any required node is lacking, no saved key begins with that sequence and the search ends.
Many trie implementations present a technique known as startsWith for this preliminary verify. It returns true when the entire prefix path exists and false when traversal fails. Autocomplete retrieval continues past that time, exploring the descendants of the prefix node and gathering the paths that finish at terminal markers.
Typically, a system wants to indicate what number of matches exist or place probably the most often chosen solutions first. Builders can help these capabilities by way of:
- Prefix counters: These report what number of saved keys share the trail to every node. When the traversal reaches the tip of a prefix, the system can learn the counter at that node to return the variety of matches with out exploring each descendant. The counters are adjusted every time a key’s added or eliminated.
- Choice scores: Every full key can carry a rating primarily based on elements corresponding to how usually customers choose it. Autocomplete techniques will evaluate scores and place probably the most often chosen solutions first.
Time Complexity of Trie Operations
Builders use time complexity to estimate whether or not a knowledge construction will stay responsive as its inputs develop and to check it with different methods of organizing the identical information. Finding a prefix and returning all of its completions require totally different quantities of labor: An autocomplete system could attain the node for “wat” shortly, however nonetheless must discover a big department to gather each matching phrase. Large O notation describes how that work grows with out assigning a precise operating time, as precise efficiency additionally depends upon the implementation and the {hardware} on which it runs.
The desk beneath compares the time complexity of the trie operations lined on this part. It makes use of “L” for the size of a whole key and “P” for the size of a prefix. For completion retrieval, C represents the variety of descendant nodes visited whereas gathering the outcomes.
Operation | Time Complexity |
|---|---|
Actual Search | O(L) |
Insertion | O(L) |
Deletion | O(L) |
Prefix Test | O(P) |
Retrieve All Completions | O(P+C) |
Implementing a Trie in Java
Implementing a trie in Java begins with deciding how every node will retailer and retrieve the kid that corresponds to the following character in a key. Java implementations generally handle these connections with arrays or maps, relying on the characters the keys could comprise and the quantity of reminiscence obtainable.
Beginning with the node design, we’ll construct a runnable Trie class that makes use of a HashMap<Character, TrieNode> and helps insertion, actual search, prefix checks, and deletion.
Designing a TrieNode Construction
Each operation within the trie strikes by way of TrieNode objects, so the node design determines how the code finds the following character and acknowledges a whole key. Every node wants a set of kid references and a boolean flag indicating whether or not the trail ends at that time.
Java builders usually select between two methods of storing the kid references:
-
Mounted array: An array corresponding to
new TrieNode[26]reserves one place for each lowercase English letter. The code can discover a youngster instantly from the character’s place within the alphabet, however each node allocates all 26 references even when it makes use of just one or two. -
Map: A
Map<Character, TrieNode>creates entries just for youngster characters that exist. This makes it appropriate for sparse nodes, which use solely a small proportion of the characters they might doubtlessly comprise. A map can accommodate uppercase letters, areas, and punctuation with out assigning every character a hard and fast place, though that flexibility carries some further overhead.
Little one nodes can be held in a linked listing. This avoids allocating a hard and fast array, however discovering a specific character could require checking the kids one by one. Maps usually present a extra sensible possibility when nodes could have a number of kids.
import java.util.HashMap;
import java.util.Map;

personal static remaining class TrieNode {
    personal remaining Map<Character, TrieNode> kids = new HashMap<>();
    personal boolean endOfWord;
}
The kids map associates every attainable subsequent character with the node that continues its path. Java collections require object sorts as generic arguments, so the map makes use of the Character wrapper for the primitive char sort. The node doesn’t must retailer its personal character as a result of the dad or mum map already holds that info. The endOfWord area stays false till an inserted key ends on the node, at which level the insert operation adjustments it to true.
An abnormal class works higher than a Java report for TrieNode as a result of insertion and deletion should change its endOfWord area. Data are designed primarily as concise information carriers whose part fields can’t be reassigned, making them extra appropriate for values corresponding to an autocomplete consequence containing a phrase and its rating:
personal report Suggestion(String phrase, int rating) {}Implementing Insert, Search, and startsWith
The Trie class owns a root node that anchors each saved path. Its insert technique provides or extends these paths, whereas a personal findNode technique handles the traversal shared by actual searches and prefix checks. Centralizing that logic retains search and startsWith constant and permits them to use totally different situations to the ultimate node.
The next runnable instance builds a Trie class with insertion and lookup strategies. Put it aside as Trie.java:
import java.util.HashMap;
import java.util.Map;
import java.util.Objects;

public class Trie {
    personal static remaining class TrieNode {
        personal remaining Map<Character, TrieNode> kids = new HashMap<>();
        personal boolean endOfWord;
    }

    personal remaining TrieNode root = new TrieNode();

    public void insert(String phrase) {
        Objects.requireNonNull(phrase, "phrase");

        TrieNode present = root;

        for (char character : phrase.toCharArray()) {
            present = present.kids.computeIfAbsent(
                    character,
                    key -> new TrieNode()
            );
        }

        present.endOfWord = true;
    }

    public boolean search(String phrase) {
        TrieNode node = findNode(phrase);
        return node != null && node.endOfWord;
    }

    public boolean startsWith(String prefix) {
        return findNode(prefix) != null;
    }

    personal TrieNode findNode(String enter) {
        Objects.requireNonNull(enter, "enter");

        TrieNode present = root;

        for (char character : enter.toCharArray()) {
            present = present.kids.get(character);

            if (present == null) {
                return null;
            }
        }

        return present;
    }

    public static void foremost(String[] args) {
        Trie trie = new Trie();

        trie.insert("water");
        trie.insert("watch");

        System.out.println(trie.search("water"));    // true
        System.out.println(trie.search("wat"));      // false
        System.out.println(trie.startsWith("wat"));  // true
        System.out.println(trie.startsWith("wax"));  // false
    }
}
Compile and run it with:
javac Trie.java
java Trie
This system ought to print:
true
false
true
false
The implementation works like this:
-
rootanchors the trie: It accommodates no character of its personal and offers the place to begin for each operation. -
insertbuilds the required path:computeIfAbsentreturns the kid node if it already exists or creates one when it’s lacking. Keys with the identical prefix subsequently reuse the nodes already current. -
findNodehandles read-only traversal: It follows the provided characters and returns the ultimate node. If a required youngster is lacking, it returnsnull. -
searchandstartsWithinterpret that node in another way:searchadditionally checksendOfWordas a result of it wants a precise key, whereasstartsWithsolely checks that the entire prefix path exists.
Every technique processes the enter as soon as, so its operating time depends upon the variety of characters provided. The instance additionally treats keys as case-sensitive and rejects null inputs. A manufacturing implementation ought to determine whether or not to normalize capitalization or apply different enter guidelines earlier than storing and looking keys.
Implementing Delete Logic
Deletion wants to find out whether or not the important thing exists and which components of its path could be eliminated safely. The general public delete technique first checks for a precise match, then passes the confirmed key to a recursive helper that works by way of the trail and removes any nodes now not in use.
Add the next strategies to the runnable Trie class from the previous part:
public boolean delete(String phrase) {
    Objects.requireNonNull(phrase, "phrase");

    if (!search(phrase)) {
        return false;
    }

    deleteNode(root, phrase, 0);
    return true;
}

personal boolean deleteNode(TrieNode present, String phrase, int index) {
    if (index == phrase.size()) {
        present.endOfWord = false;
        return present.kids.isEmpty();
    }

    char character = phrase.charAt(index);
    TrieNode youngster = present.kids.get(character);

    boolean removeChild = deleteNode(youngster, phrase, index + 1);

    if (removeChild) {
        present.kids.take away(character);
    }

    return present.kids.isEmpty() && !present.endOfWord;
}
The helper strikes ahead by way of the important thing till it reaches the terminal node, the place it clears endOfWord. As every recursive name finishes, the code works backward by way of the trail and checks whether or not the node it has simply left remains to be wanted. A baby could be eliminated solely when it has no kids of its personal and doesn’t mark one other full key.
This situation preserves overlapping entries. If the trie shops each “water” and “watch,” deleting “water” removes solely the nodes that belong solely to that phrase; the shared path and the department resulting in “watch” stay intact.
Finish-of-word markers additionally defend keys that type prefixes of longer entries. If the trie shops each “app” and “apple,” deleting “apple” stops cleanup when it reaches the node marking “app” as a whole key. Deleting “app” clears its terminal marker however preserves the remaining path as a result of “apple” nonetheless depends upon it.
Add these traces to the tip of foremost to check the strategy:
System.out.println(trie.delete("water")); // true
System.out.println(trie.search("water")); // false
System.out.println(trie.search("watch")); // true
System.out.println(trie.delete("wat"));   // false
The extra output ought to be:
true
false
true
false
Implementing Tries Throughout Programming Languages
Insertion, search, and deletion comply with the identical traversal logic throughout programming languages, though the information buildings used to retailer youngster nodes differ. The illustration of these youngster nodes influences how simple the code is to learn and adapt. It additionally determines the reminiscence required at every node and the work concerned to find the following character.
The comparability beneath exhibits the illustration generally utilized in every language and the sensible trade-offs it introduces.
Language | Typical Little one Illustration | Sensible Commerce-off |
|---|---|---|
Java |
| A map produces adaptable code that may settle for assorted characters, however |
Python |
| Dictionaries make the trie concise and straightforward to change, however every node and dictionary entry consumes substantial reminiscence. Dynamic dictionary lookups also can add traversal overhead in a big trie. |
JavaScript |
| A |
C++ |
| Arrays and express reminiscence administration can cut back traversal and allocation overhead, however the code turns into extra detailed as a result of node possession have to be outlined. An unordered map helps sparse branches at the price of hashing and extra storage per entry. |
Trie Reminiscence Utilization and Efficiency Commerce-offs
Theoretical lookup time doesn’t point out whether or not a trie will carry out nicely as soon as applied. Each character traversed corresponds to a node that occupies reminiscence and have to be accessed throughout the search; when a big dataset produces thousands and thousands of sparsely related nodes, the ensuing construction can eat substantial area and make every traversal step dearer. The good thing about a brief search path finally depends upon whether or not the implementation can symbolize and entry these nodes effectively.
Why Tries Can Turn into Reminiscence Intensive
A trie’s reminiscence use is distributed throughout its nodes, which may make the full simple to underestimate. A single node could seem light-weight, but a big dictionary creates one other every time a key introduces a personality path that isn’t already current. Reminiscence use is, subsequently, influenced by the variety of nodes the dataset requires and the quantity of area connected to every one.
A number of options of the construction can improve the reminiscence wanted:
- Mounted youngster arrays reserve capability that almost all nodes by no means use. An array with 26 positions offers one for each lowercase English letter, however a node with a single youngster leaves the opposite 25 references empty. Repeating that allocation all through the trie creates substantial unused capability.
- Bigger alphabets improve the dimensions of mounted arrays. Supporting uppercase letters or punctuation requires extra positions at each node. Character units with much more attainable values make a hard and fast place for each impractical.
- Every node carries its personal storage overhead. Alongside its youngster references, a node could comprise a terminal marker and the construction used to handle its kids. Languages and runtimes can add additional reminiscence for object bookkeeping or alignment, and people small prices accumulate throughout the trie.
- Restricted prefix sharing produces extra unbiased paths. Datasets whose keys diverge close to the start require extra branches than collections with lengthy frequent prefixes. Below these situations, a trie could eat extra reminiscence than a hash desk or binary search tree storing the identical keys.
I pay explicit consideration to buildings that stay in reminiscence for the applying’s total runtime. Momentary working information could be launched as soon as an operation finishes, however a trie could proceed occupying reminiscence in order that its keys stay instantly searchable. Because the trie grows, it leaves much less reminiscence obtainable for the applying’s different operations.
Reminiscence Optimization Methods for Tries
Trie optimization can cut back the area connected to every node or cut back the variety of nodes required to symbolize the keys. A sparsely branching trie wastes reminiscence inside outsized youngster buildings, whereas lengthy paths with out branches create intermediate nodes that contribute little info of their very own. The next optimization methods allocate youngster storage extra selectively and cut back the variety of nodes wanted to symbolize the identical keys.
Use Maps for Sparse Little one Storage
Maps are best when most nodes have few kids. As branching turns into denser, the overhead connected to every map entry can outweigh the area saved, making a hard and fast array extra environment friendly.
Mix a Bitmap With a Compact Little one Array
The bitmap data which characters have kids, whereas the array accommodates solely the corresponding node references. When a personality is requested, the implementation checks its bit and makes use of the previous bits to find the proper array place. This preserves compact storage with out making a separate map entry for each youngster.
Restrict the Supported Alphabet The place the Utility Permits It
A trie constructed solely for lowercase English phrases can map characters to 26 positions with out reserving area for uppercase letters or different symbols. Enter ought to solely be normalized when distinctions corresponding to capitalization carry no that means for the applying.
Compress Paths That Comprise No Branching Choices
A sequence of single-child nodes could be represented as one path phase containing a number of characters. Radix bushes and compressed tries apply this method to cut back node depend and shorten traversal.
Share Equivalent Subtrees in Static Dictionaries
When separate paths result in precisely the identical remaining character sequences, they will reference one saved subtree. This produces a directed acyclic construction reasonably than a strict tree and makes updates extra sophisticated, so it’s best suited to collections that change sometimes.
Change the Little one Illustration as a Node Turns into Denser
A node could start with a small listing or compact map and swap to an array after it develops sufficient kids for direct indexing to justify the reserved area. This hybrid method adapts the storage price to the branching sample of every node.
Sensible Efficiency Concerns
The time required for a trie question depends upon what the system should return and the way the related department is structured. The primary efficiency elements embody:
- Sort of question: A precise search follows one path and checks its terminal marker. Autocomplete includes exploring the nodes beneath the prefix, so finding the prefix could take far much less time than gathering and rating its rivals.
- Size of enter: Each further character provides one other traversal step. A four-character product code subsequently requires fewer steps than a twenty-character identifier.
- Distribution of the keys: Shared opening characters permit the trie to reuse one path, however a prefix with hundreds of completions can create a big department to go looking. Setting a consequence restrict permits the traversal to cease as soon as it’s collected sufficient solutions.
- Storage and testing situations: Nodes saved shut collectively in reminiscence are usually quicker to entry than nodes scattered throughout separate areas. Time-complexity evaluation can’t account for each implementation and {hardware} distinction, so it’s necessary to check efficiency utilizing the sorts of keys and queries the applying will deal with in actuality.
Evaluating Tries to Different Knowledge Constructions
Tries are designed round prefix traversal, which provides them a bonus when searches start with incomplete keys. That benefit shouldn’t be so vital when an utility solely wants actual matches or should keep keys in sorted order.
Evaluating tries with hash tables and binary search bushes exhibits how the anticipated searches, the relationships between saved keys, and the obtainable reminiscence ought to information the selection of information construction.
Benefits and Disadvantages of Trie Constructions
Some great benefits of utilizing a trie are most obvious with autocomplete, the place every new character narrows the search to at least one department of saved keys. That group is much less economical when the keys have few prefixes in frequent, because the trie creates extra separate nodes with out gaining as a lot path reuse.
The next desk weighs these retrieval advantages in opposition to the corresponding reminiscence and implementation prices.
Space | Benefit | Drawback |
|---|---|---|
Prefix Retrieval | The trie follows the provided characters on to the department containing attainable matches. | Returning each match could require exploring numerous nodes beneath that prefix. |
Shared Prefixes | Associated keys reuse the identical opening path, decreasing the variety of occasions these characters have to be represented. | Keys that diverge close to the foundation create extra separate paths and obtain much less profit from this reuse. |
Traversal Size | The steps required to find a key or prefix rely totally on its size, not the full variety of saved keys. | Each character requires a separate node entry, and the chosen youngster illustration impacts the velocity of that entry. |
Ordered Retrieval | Visiting youngster nodes in character order returns the saved keys lexicographically. | Implementations that use unordered maps should type the kid characters earlier than producing ordered outcomes. |
Reminiscence Use | Shared paths can cut back duplication when many keys have prefixes in frequent. | Node objects, youngster references, and unused array positions could make a trie bigger than a hash desk or binary search tree containing the identical keys. |
Implementation | Insertion, actual search, and prefix checks use the identical primary traversal sample. | Deletion, ranked autocomplete, and reminiscence optimization require further logic and testing. |
Trie vs. Hash Desk
A hash desk makes use of the entire key to calculate the place its worth ought to be saved. This makes it well-suited to exact-match searches, because the lookup can transfer on to the anticipated location after processing the important thing. A partial key doesn’t present the identical route: The hash calculated for “wat” bears no helpful relationship to these calculated for “watch” or “water.” Discovering each key with that prefix subsequently requires scanning the desk or sustaining a separate prefix index.
Hash tables additionally have a tendency to make use of much less reminiscence when strings have little in frequent, since they retailer every key as a whole worth as a substitute of making a node for each character path. This makes a hash desk usually preferable when searches use full keys, whereas a trie is healthier suited to workloads pushed by prefix retrieval.
Trie vs. Binary Search Tree
A binary search tree shops full keys in line with their relative order. Every comparability sends the search to the left or proper department till it finds the requested key or reaches an empty path. A balanced tree limits the variety of comparisons required, however prefix retrieval nonetheless wants further logic to find the primary matching key and proceed by way of the ordered entries till the prefix adjustments.
That ordering makes binary search bushes helpful for vary queries, corresponding to retrieving all product codes from A100 by way of A500, and sorted traversal, like itemizing buyer names alphabetically. They might additionally use much less reminiscence than a trie when the saved keys have few opening characters in frequent. To maintain searches environment friendly, a balanced tree could must rearrange its nodes after an insertion or deletion in order that paths don’t get disproportionately lengthy. Trie updates, however, comply with the characters in the important thing with out reorganizing unrelated branches. A trie is healthier suited to direct prefix retrieval; a binary search tree is extra acceptable when the applying wants broader types of ordered entry.
Variants and Optimized Trie Constructions
As a typical trie assigns a separate node to each character, lengthy paths with little branching are costly to retailer. It’s additionally designed round full character strings, so binary keys and substring searches name for various traversal patterns.
Optimized trie variants alter how paths or branches are represented to cut back reminiscence use and help these extra specialised types of retrieval.
Radix Bushes and Compressed Tries
A radix tree, additionally known as a compressed trie, replaces a series of nodes with a single path phase when no branching happens alongside that route. If a trie shops “compact,” “compute,” and “pc,” for instance, the usual construction creates separate nodes for “c,” “o,” “m,” and “p” earlier than branching to “a” and “u.” A radix tree can retailer “comp” as one phase and department solely the place the phrases differ.
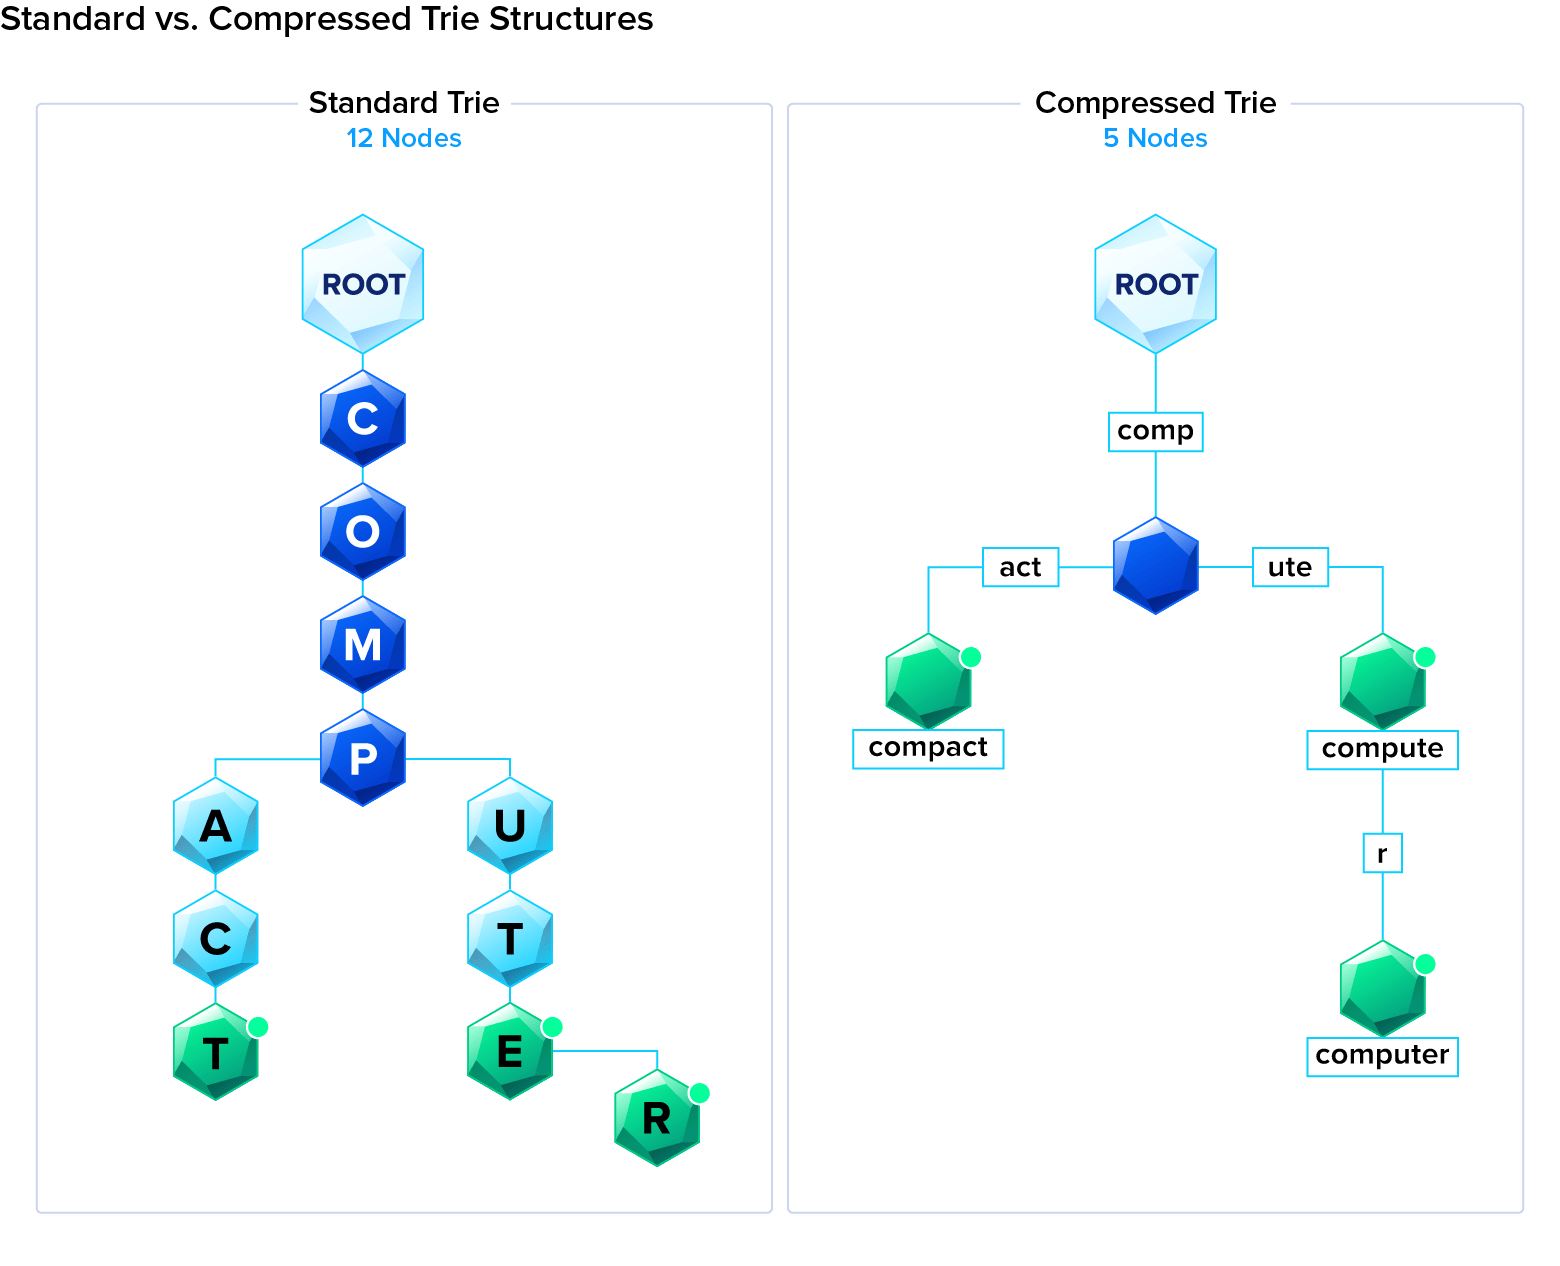
Eradicating the intermediate nodes reduces reminiscence use and the variety of node-to-node actions throughout traversal. The search should nonetheless evaluate each character within the phase, whereas insertion and deletion might have to separate or mix segments as keys change.
Bitwise Tries and Binary Prefix Bushes
A bitwise trie makes use of the binary digits 0 and 1 as its traversal keys. The values 1010 and 1011, for instance, comply with the identical path by way of 101 earlier than branching on the remaining bit. Since each node can have solely two kids, the construction is well-suited to fixed-length binary values corresponding to IP addresses.
Community routers use this construction to seek out probably the most particular routing entry that matches a vacation spot deal with. If an deal with matches entries for each 10 and 101, the longer prefix 101 offers the extra exact route. This course of is called longest-prefix matching.
Suffix Bushes and Specialised Trie Variants
A suffix tree is helpful when a system repeatedly searches the identical physique of textual content for sequences which will start wherever inside it. A genomic evaluation program can use one to find many brief DNA patterns throughout an extended sequence.
A typical trie can solely comply with a string from its starting, whereas a suffix tree shops a compressed illustration of the suffix that runs from every place to the tip. For “banana,” these parts are “banana,” “anana,” “nana,” “ana,” “na,” and “a.” A seek for “ana” follows one path within the tree, which may report that the sequence begins on the second and fourth characters of “banana.” Utilized to genomic information, the identical construction permits software program to index an extended DNA sequence as soon as after which find each prevalence of a shorter sample with out scanning the entire sequence once more.
Storing a path from each beginning place can require substantial reminiscence, so implementations normally compress sections that comprise no branches. The development and storage prices make suffix bushes extreme for abnormal autocomplete or exact-match lookup.
Actual-world Purposes of Trie Knowledge Constructions
The flexibility to keep away from repeated scans of the entire dataset has made tries beneficial in techniques the place retrieval should stay responsive because the variety of entries grows. The next examples illustrate a number of the commonest real-world functions of the trie information construction and study how every system makes use of it.
Autocomplete and Predictive Textual content Techniques
Autocomplete and predictive textual content each use tries to supply solutions from incomplete enter. Autocomplete suggests attainable endings for the present phrase or question, whereas predictive textual content may think about the phrases that got here earlier than it. A trie helps these techniques by way of a number of associated operations:
- Candidate retrieval: The system follows the entered prefix and collects full keys from the department beneath it.
- Suggestion rating: Saved scores permit the system to prioritize candidates primarily based on elements corresponding to choice frequency or relevance.
- Outcome caching: Steadily accessed prefix nodes can retain a brief listing of their highest-ranked solutions, avoiding a search of the entire department after each keystroke.
- Ongoing updates: Rankings and cached outcomes have to be refreshed as saved entries or consumer choice patterns change.
Spell Checkers and Dictionary Techniques
Spell checking combines actual lookup with a seek for believable options. A dictionary trie can verify whether or not an entered phrase is saved and, when it isn’t, prohibit the correction search to character paths that would nonetheless produce a sound phrase. Widespread makes use of embody:
- Phrase validation: The spell checker follows the entered characters and accepts the phrase provided that the ultimate node has a terminal marker.
- Correction technology: The traversal checks attainable insertions, deletions, or substitutions and abandons a path as soon as it may well now not produce a sound dictionary phrase.
- Candidate rating: Frequency values assist place frequent phrases forward of much less doubtless corrections.
- Dictionary retrieval: A terminal node can reference info related to the phrase, corresponding to its definition or grammatical class.
IP Routing and Community Prefix Matching
Community visitors travels in packets, that are small items of information containing a vacation spot IP deal with. A router reads that deal with to find out the place every packet ought to be despatched subsequent. Routing tables describe teams of addresses as binary prefixes, and a couple of entry could match the identical vacation spot. A bitwise trie helps this routing course of by way of the next options:
- Prefix storage: Every marked node represents a community prefix and holds the instruction for forwarding packets that match it.
- Deal with traversal: The router follows the vacation spot deal with one bit at a time, transferring by way of the corresponding binary path.
- Route choice: The traversal retains the deepest matching entry it encounters as a result of the longest prefix describes the smallest and most particular deal with vary.
- Path compression: Sections with out branches could be saved as longer segments, decreasing the variety of nodes required for a big routing desk.
Selecting When to Use a Trie
The frequent thread throughout trie functions is progressive elimination. Every character guidelines out branches that may’t comprise a match, turning partial enter right into a route by way of saved information. The identical precept helps dictionary searches, community routing, and specialised buildings that find patterns.
Precise efficiency, although, nonetheless depends upon how the trie is constructed. Sparse branches, outsized youngster arrays, and broadly scattered nodes could make an environment friendly traversal costly to retailer and execute. The node illustration ought to subsequently replicate how the saved keys department, decreasing unused capability with out making youngster nodes tough to find. The place searches repeatedly rely upon prefixes, a trie information construction retains the work directed towards the related a part of the dataset from the primary traversal step.